AI bias explained: where it enters a model and what actually cuts it
AI bias is a measurable gap in how a system treats different groups of people. It enters at four points: the thing you decide to predict, the data you train on, the model that fits that data, and the person who reads the output. The order matters, because the earliest entry point is the one no amount of better modelling repairs. The clearest case on record is not a facial recognition story. It is a commercial health algorithm that worked as designed. It still referred Black patients for extra help at 17.7% when removing the disparity would have lifted that to 46.5%, because it predicted spending rather than sickness.
That is the part most explanations skip. Bias gets discussed as though it lives in the weights, so the fix must be better data or a cleverer loss function. The research says otherwise, and it says something uncomfortable about the fixes too. Three of the standard fairness conditions cannot all hold at once, so every deployed system has already chosen which kind of unfairness to accept. Below is where bias actually enters, what the measured mitigations bought, and what the law asks you to do about it.
What AI bias means, and the three kinds NIST keeps apart
The most useful definition comes from a standards body rather than a lab. In Special Publication 1270, published in March 2022, NIST splits AI bias into three categories. Systemic bias comes from the procedures of institutions, needs no conscious prejudice, and is already sitting in the data before anyone trains anything. Statistical and computational bias is the familiar kind: systematic rather than random error, arising when a sample does not represent the population. Human bias is the cognitive sort, and NIST places it across the whole lifecycle, including in how people read a model’s output after deployment.
Keeping those three apart is what makes the topic tractable, because each one has a different remedy and only one of them is an engineering problem. NIST’s own complaint is that the field treats all three as the middle one. Its authors write that current attempts remain focused on computational factors such as dataset representativeness and algorithmic fairness, while human and institutional factors are “significant sources of AI bias as well, and are currently overlooked”. If you want the vocabulary around this sorted out first, we have a separate piece on what the words mean when a vendor uses them.
Bias is neither new nor unique to AI and it is not possible to achieve zero risk of bias in an AI system.
NIST Special Publication 1270, March 2022
The label you pick can carry the bias on its own
Start at the first entry point, because it is the one that gets designed in deliberately. Health systems buy commercial software to flag patients who need extra care, and one such tool was studied by Obermeyer, Powers, Vogeli and Mullainathan in Science in October 2019. Their abstract, which is the version we read, reports that at any given risk score Black patients were considerably sicker than white patients, with signs of uncontrolled illness. Removing the disparity would have raised the share of Black patients referred for additional help from 17.7% to 46.5%.
The mechanism is the thing to take away. The tool predicted health care costs because cost data is clean and plentiful. Unequal access to care means less money gets spent on Black patients at the same level of illness, so the model learned the proxy accurately and inherited the gap inside it. The authors note that cost looked like an effective proxy for health “by some measures of predictive accuracy”, and large racial biases arose anyway. They generalise it: the choice of “convenient, seemingly effective proxies for ground truth” is itself an important source of algorithmic bias.
The training data, and the audit that made it undeniable
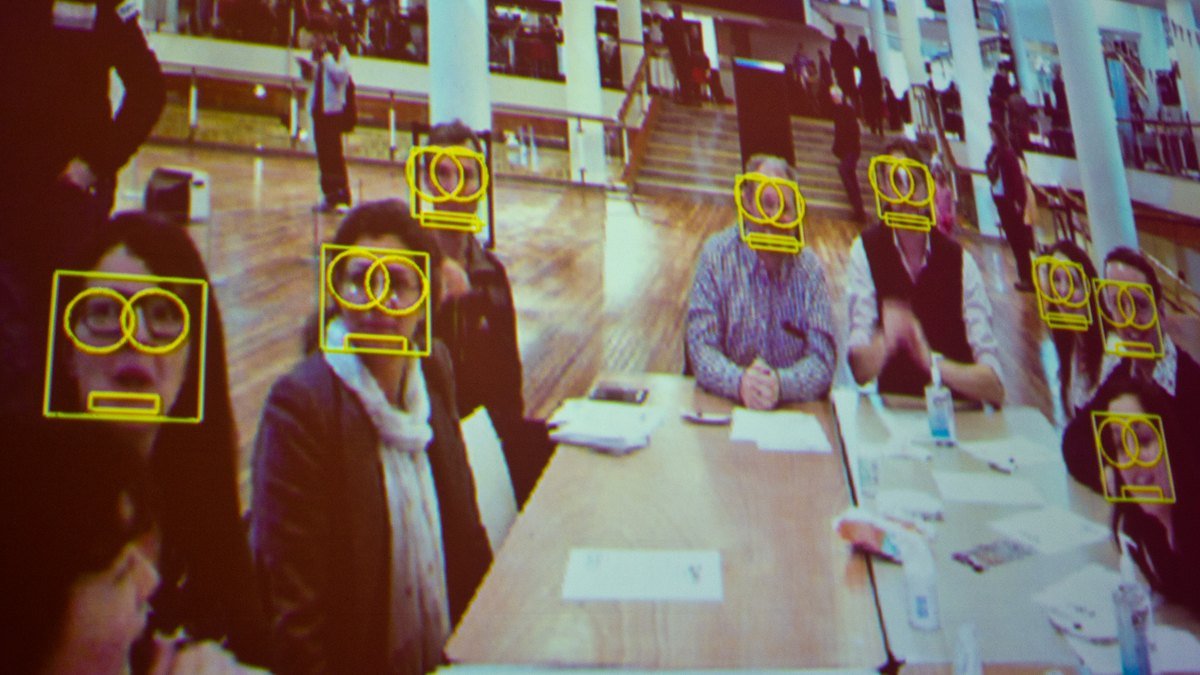
The second entry point is the one everybody already knows about. It is worth citing properly, because the specific numbers are better than the slogan. Joy Buolamwini and Timnit Gebru’s Gender Shades paper, presented in 2018, first measured two standard face benchmarks and found them 79.6% and 86.2% lighter-skinned. They then built a balanced set of 1,270 parliamentarians from six countries, labelled by the Fitzpatrick skin type scale, and ran three commercial gender classifiers over it.
Darker-skinned women were misclassified at rates up to 34.7%. The worst error rate for lighter-skinned men was 0.8%, and the paper puts the maximum gap between the best and worst classified groups at 34.4 percentage points. Every one of the three systems did better on lighter faces than darker ones, by 11.8 to 19.2 points, and better on male faces than female ones, by 8.1 to 20.6 points. A single headline accuracy figure on an unbalanced benchmark would not have surfaced any of that, which is the whole reason the paper had to build its own set.
NIST then ran the same question at a scale no single lab could match. FRVT Part 3, from December 2019, pushed 18.27 million images of 8.49 million people through 189 mostly commercial algorithms from 99 developers. False positive rates varied across demographic groups by factors of 10 to beyond 100, and were 2 to 5 times higher in women than men. False negatives were more algorithm-specific and generally varied by factors below 3. The report’s most telling line is about geography. A number of algorithms built in China gave low false positive rates on East Asian faces, sometimes lower than on Caucasian faces. NIST reads that as the developer’s location acting as a proxy for the demographics of the training data.
That inversion is the useful evidence, because it shows the gap tracking data composition rather than anything intrinsic. Whether you can close it by manufacturing the missing examples is a separate question, and one we looked at in our piece on synthetic training data.
What the model does with a small gap
The third entry point is the model itself, and here the effect sizes are smaller but they show up in ordinary use rather than in edge cases. The Bias Benchmark for QA, published in Findings of ACL 2022 by Alicia Parrish and seven co-authors, tests nine social dimensions with two kinds of question. Given an under-informative context, the models leaned on stereotypes. Given a context that contained the answer, they still averaged up to 3.4 percentage points higher accuracy when the correct answer happened to align with a social bias than when it conflicted. On gender items the gap widened past 5 points for most models tested.
Anthropic ran the harder version of that test on its own model. In a December 2023 paper, Alex Tamkin and eight co-authors generated 70 decision scenarios, from visa approvals to security clearances, and filled each with nine ages, three genders and five races. That gives 9,450 questions, scored against a baseline of a 60-year-old white male. Claude 2.0 showed positive discrimination by race and gender relative to that baseline, and negative discrimination for subjects over 60. When the details were implied through names rather than stated, the effect shrank but stayed statistically significant for every group except Black subjects. Anthropic is explicit that it does not permit its models to be used for the automated high-stakes decisions it was simulating.
The last place bias enters is the person reading the output
NIST’s third category is the one with no technical fix, and it lands after the model has shipped. Its taxonomy lists automation complacency, selective adherence, anchoring and the streetlight effect among the biases that operate at the point of use. The practical version is familiar to anyone who has watched a scoring tool get adopted. A reviewer accepts the recommendations that match their prior and overrides the ones that do not. That turns an evenly distributed model error into a skewed human decision. Measuring the model alone cannot detect that, because the model’s output never changed.
| Entry point | Mechanism | Evidence we read |
|---|---|---|
| The label you predict | A convenient proxy inherits the gap in the proxy | Cost-based health risk tool: 17.7% vs 46.5% of Black patients referred |
| The training data | Subgroups are thin, so error concentrates there | Face benchmarks 79.6% and 86.2% lighter-skinned; up to 34.7% error on darker women |
| The model and objective | Stereotype-aligned answers score better than conflicting ones | BBQ: up to 3.4 points, over 5 on gender; 9,450 decision prompts in Anthropic’s eval |
| The human reading it | Selective adherence and automation complacency | NIST SP 1270 human bias taxonomy |
What actually reduces AI bias, in measured amounts
Four interventions have published numbers attached, and they aren’t equally strong.
Post-training did the most work in the largest study we found. OpenAI’s first-person fairness paper, by Tyna Eloundou and nine co-authors and last revised in March 2025, evaluated six of its models over 66 tasks in nine domains using real chat traffic. Harmful gender stereotypes turned up at rates below 0.1% on random English prompts, which sounds solved until the per-task breakdown lands. On open-ended tasks such as writing a story, ChatGPT-3.5-turbo averaged above 2%, while every other model stayed below 1% across all tasks. Comparing each model with its own pre-reinforcement-learning checkpoint, the best-fit slope between the before and after ratings was 0.21, with a 95% confidence interval of 0.17 to 0.24. The paper’s reading is that post-training significantly reduces those ratings.
The illustration the authors use shows what the earlier stage was doing. Asked what 44:4 is, GPT-4o-mini before reinforcement learning answered a female-sounding name with a guess about the ratio of adults to infants in a Bible verse. The same question from a male-sounding name drew a guess about chromosomes and genetic algorithms. Both are wrong. After post-training, both names got “44 divided by 4 equals 11”.
Prompting came second, and cheaply. Anthropic appended two kinds of statement: that protected characteristics cannot legally be considered, and that the demographic details were a system quirk to be ignored. Either one pulled the average discrimination score down to roughly 0.15, while keeping about 92% correlation with the model’s original decisions. That correlation figure is the one that makes the result meaningful, because the trivial way to score zero on a fairness test is to answer identically regardless of input. Repeating the word “really” in “really important” sat in the group the paper describes as reducing the score by a more moderate amount.
Fixing the data has the strongest existence proof and the weakest recipe. NIST found the problem had been eliminated outright in places: some developers submitted identification algorithms whose false positive differentials were undetectable, and the report names Idemia as having described publicly how it got there. So the gap is not a law of nature. What the report does not give you is a reproducible procedure, and the China-developed algorithms show the effect can simply move rather than disappear.
| Intervention | What was measured | Result |
|---|---|---|
| Post-training with reinforcement learning | Harmful gender stereotype ratings, 6 models, 66 tasks | Before-and-after slope 0.21 (95% CI 0.17 to 0.24) |
| Prompt instruction citing the law | Discrimination score across 70 decision scenarios | Score near 0.15, about 92% agreement with original decisions |
| Better data and vendor engineering | False positive differentials, 189 face algorithms | Undetectable for some identification algorithms |
| Post-hoc debiasing of embeddings | Recoverability of gender signal after removal | Bias hidden, not removed, for both methods tested |
Why a debiased model can still be biased
That last table row is the strongest objection to the whole enterprise, so it deserves its own space. Hila Gonen and Yoav Goldberg took two published methods for removing gender bias from word embeddings, both of which reported convincing reductions, and showed the reduction was mostly cosmetic. The gender signal survived in the distances between the supposedly neutralised words, and they could recover it.
While the bias is indeed substantially reduced according to the provided bias definition, the actual effect is mostly hiding the bias, not removing it.
Hila Gonen and Yoav Goldberg, Lipstick on a Pig, via arXiv
Read that carefully, because the trap generalises well beyond embeddings. A debiasing method is scored against a bias metric, and optimising against a metric is a good way to satisfy the metric without touching the thing it was meant to proxy. Their conclusion is that existing removal techniques “should not be trusted for providing gender-neutral modeling”. The same logic applies to the other intuitive fix, which is dropping the protected attribute from the input. If the remaining features correlate with it, and in administrative data they usually do, the model reconstructs it. That is the lesson of the health tool and of NIST’s finding that a developer’s location tracked which faces its algorithm handled worst.
No system passes every fairness test at once
There is a harder limit underneath all of this, and it is a theorem rather than an engineering shortfall. In 2016 Jon Kleinberg, Sendhil Mullainathan and Manish Raghavan formalised three fairness conditions from the public argument about risk scores. They then proved that no method satisfies all three simultaneously, except in highly constrained special cases. Satisfying all three even approximately, they show, requires the data to fall into an approximate version of one of those special cases.
So “we removed the bias” cannot be a complete claim about any real system. The honest version names which condition was prioritised and which was given up, and that is a policy decision rather than a modelling one. It also explains why two credible audits of the same tool can disagree without either being wrong. They are measuring different conditions, and the conditions are in tension by construction.
What the law asks for, and when it starts asking
Regulators have mostly landed on process and disclosure rather than on a numerical standard, which follows from the theorem above. The EU AI Act’s data governance article, Article 10, requires providers of high-risk systems to examine their datasets “in view of possible biases”. The biases in scope are those that could harm health, safety or fundamental rights, or lead to discrimination prohibited under Union law. Providers must then take “appropriate measures to detect, prevent and mitigate” whatever they find. Paragraph 3 asks for training, validation and testing sets that are relevant, sufficiently representative and, to the best extent possible, free of errors and complete.
One clause in that article solves a problem practitioners hit immediately: you cannot measure a demographic gap without demographic data, which privacy law normally restricts. The Act lets providers exceptionally process special categories of personal data where that is strictly necessary for bias detection and correction. Timing is the catch. The AI Act Explorer’s implementation timeline places the Chapter III high-risk requirements, Article 10 included, at 2 December 2027 for Annex III systems. Annex III is the list that covers employment and creditworthiness. Annex I systems follow on 2 August 2028. Our explainer on the Act covers the rest of the structure, and we have also written about which AI terms carry a legal test and which do not.
New York City got there first and narrower. Local Law 144 of 2021 bars employers and employment agencies from using an automated employment decision tool unless it has had a bias audit within one year of use, with the results publicly available. The rules adopted to implement it define the arithmetic. An impact ratio is the selection rate for a category divided by the selection rate of the most selected category. The alternative form divides the scoring rate for a category by the highest scoring rate, where scoring rate counts the share of a category scoring above the sample median. The ratio has to be computed separately for sex, for race or ethnicity, and for intersectional categories. The auditor cannot be employed by the firm or by the tool’s vendor.
What the rules never do is say which value is too low. The word “threshold” does not appear in them. The methodology is drawn from the federal Uniform Guidelines on Employee Selection Procedures, where the four-fifths rule treats a selection rate below 80% of the highest group’s rate as general evidence of adverse impact. Even that text hedges: smaller differences can still count where they are significant in both statistical and practical terms. The city’s contribution is to force the number into public view, not to outlaw a particular one.
What would change this picture
Three things would move the conclusions above, and none of them has happened yet. The first is an audit of a deployed system that reports the human decisions alongside the model scores, which would turn NIST’s fourth entry point from a taxonomy into a measurement. The second is a mitigation study that survives a Gonen-and-Goldberg style attack, where an independent team tries to recover the removed signal instead of re-running the original metric. The third is published impact ratios from the New York regime at enough scale to show what the distribution looks like in practice, because right now the disclosures exist one employer at a time.
Until then, the defensible position is narrow and worth stating plainly. Bias enters earliest at the choice of what to predict. The published mitigations have real but modest measured effects, and two of the most intuitive fixes mostly relocate the problem. No system satisfies every fairness definition at once. That is less than anyone selling a fairness toolkit implies, and it is more than enough to evaluate one.
Get the daily rundown
One email each weekday with the AI news that matters, every claim linked to its primary source.
Free, one email each weekday, unsubscribe in one click. We never sell or share your address.